
We have reached a point where artificial intelligence answers more business questions in a day than most internal teams manage in a week. Sales teams rely on it for prospect research, marketers use it to shape messaging, and executives increasingly consult it before making decisions. That scale matters, because when an error appears in a system used this widely, it does not stay small. Losses tied to AI hallucinations are projected to exceed $100 billion in 2025, up sharply from $67.4 billion in 2024 (AllAboutAI, 2025).
This article examines how hallucinations emerge in search-oriented large language models, why some systems fail more often than others, how sentiment has shifted during 2025, and where the real financial damage is occurring. It also looks at how AI search differs from Google, and why search marketing strategies must change if businesses want visibility without inheriting the risk.
What are AI hallucinations in search LLMs?
AI hallucinations are instances where a language model generates information that appears credible but has no factual basis or is materially wrong. In search contexts, this often means invented statistics, fabricated citations, incorrect summaries, or confident answers to questions where no reliable data exists. The defining feature is not error alone, but fluency combined with falsehood.
These hallucinations occur because LLMs are designed to prioritise linguistic coherence over verification. In creative use cases this behaviour is tolerable, sometimes useful. In search, customer support, compliance, and research, it becomes corrosive. Search-oriented models are expected to compress reality into a single response, yet they lack an internal concept of truth. They optimise for plausibility, not accuracy, which turns every output into a probabilistic guess rather than a retrieved fact.
How do LLMs work?
Large language models function as probabilistic sequence predictors. Trained on vast corpora of text, they learn patterns that allow them to predict the most likely next token given a prompt. Transformer architectures and attention mechanisms enable them to weigh contextual relevance across long passages, producing responses that read as authoritative.
Why do AI Hallucinations Occur?
This process differs fundamentally from database or index-based retrieval systems. A database either contains a fact or it does not. If the data is missing, the system returns nothing. An LLM cannot return nothing. Faced with a gap, it reconstructs an answer from similar patterns seen during training. That reconstruction is where hallucinations form.
Three technical factors dominate. Noisy training data introduces outdated, biased, or contradictory patterns that the model cannot resolve. Probabilistic sampling allows low-probability but fluent responses to surface, particularly in complex or multi-step queries. Lack of real-time grounding means that without external verification layers, the model cannot check whether an answer corresponds to reality. The result is confident fabrication, especially in niche, regulated, or fast-moving domains.
How do hallucinations compare between different LLMs?
Hallucination rates vary widely across models, tasks, and evaluation methods. Benchmarks published throughout 2025 show improvement compared to earlier generations, but no system consistently avoids the problem.
Recent evaluations place Claude 4.5 Haiku at 26% hallucination rate, the lowest among widely deployed models, with strong factual consistency across general knowledge tasks (Vectara Leaderboard, Dec 2025). Claude 4.5 Sonnet performs slightly worse at 48%, with reliability varying sharply by domain (AIMultiple Benchmark, Dec 2025). GPT-5.1 shows improvement over earlier OpenAI models but still hallucinates in 52% of complex queries, particularly those requiring synthesis across sources (Visual Capitalist, Nov 2025).
Open-source and frontier systems show higher volatility. DeepSeek records 80–82% hallucination rates in medical and long-form reasoning tasks (Mount Sinai Study, Aug 2025). Grok-3 performs worst, with 94% of answers incorrect in some controlled tests (Visual Capitalist, Nov 2025). Perplexity, which integrates retrieval-augmented generation, sits at 37%, demonstrating how grounding mechanisms reduce but do not remove the risk (5GWorldPro, Dec 2025).
What percentage of AI responses are hallucinations?
Across the industry, hallucination rates now cluster lower than in 2023 and 2024, but they remain material. General-purpose models hallucinate in 8–38% of responses depending on task and prompt structure, with averages between 15–30% for search-style queries (Lakera Report, Oct 2025). In adversarial or stress-tested scenarios, rates spike to 65.9% (medRxiv Study, Mar 2025).
Domain-specific data exposes sharper risk. Legal research tasks show hallucination rates above 75%, driven by citation fabrication and misinterpretation of precedent (AI21 Labs Study, May 2025). Medical models perform better overall, with 4.3–10% error rates, but the cost of a single failure is far higher (Drainpipe.io Analysis, 2025). General knowledge queries remain comparatively safer at 9.2%, explaining why casual users often underestimate the scale of the issue.
What work to happening to reduce hallucinations?
Mitigation efforts have intensified, focusing on architecture rather than prompt discipline alone. Retrieval-augmented generation anchors responses in external sources, reducing hallucination rates by 60–80% in controlled studies (JMIR Cancer Study, Sept 2025). Fine-tuning with domain-specific datasets and stricter evaluation benchmarks has improved reliability in enterprise deployments (OpenAI Research Paper, Sept 2025).
Agent-level tooling has also matured. Observability platforms now track prompt-response chains, flagging inconsistencies before outputs reach users (GetMaxim.ai, Sept 2025). Interpretability research has begun to expose internal failure modes, with Anthropic’s circuit-level analysis reducing performance degradation under stress (Wikipedia, 2025). Despite this progress, probabilistic generation remains core to LLM design, making complete elimination structurally unlikely (New Scientist, May 2025).
What social media is saying about hallucinations in 2025
Online discussion during 2025 has shifted from novelty to fatigue. Practitioners increasingly describe hallucinations as an operational risk rather than a theoretical limitation. Long-form commentary highlights erosion of trust in AI-generated answers, particularly where systems fabricate sources or statistics (Medium, Nov 2025). Mainstream coverage reflects similar concerns, framing hallucinations as a brake on adoption in regulated industries (New York Times, May 2025).
Business sentiment mirrors this unease. Surveys indicate 77% of organisations now cite hallucinations as a primary concern when deploying AI at scale (Fullview.io, Nov 2025). At the same time, improvements in retrieval-based systems have tempered outright rejection. The tone is no longer dismissive or alarmist. It is cautious, shaped by experience rather than speculation.
What is the difference between LLM search and Google search?
Search behaviour is fragmenting. Google continues to operate as an index-based retrieval engine, crawling and ranking pages that users can inspect and verify. LLM-based search systems synthesise answers directly, often without exposing underlying sources. That distinction alters both risk and visibility.
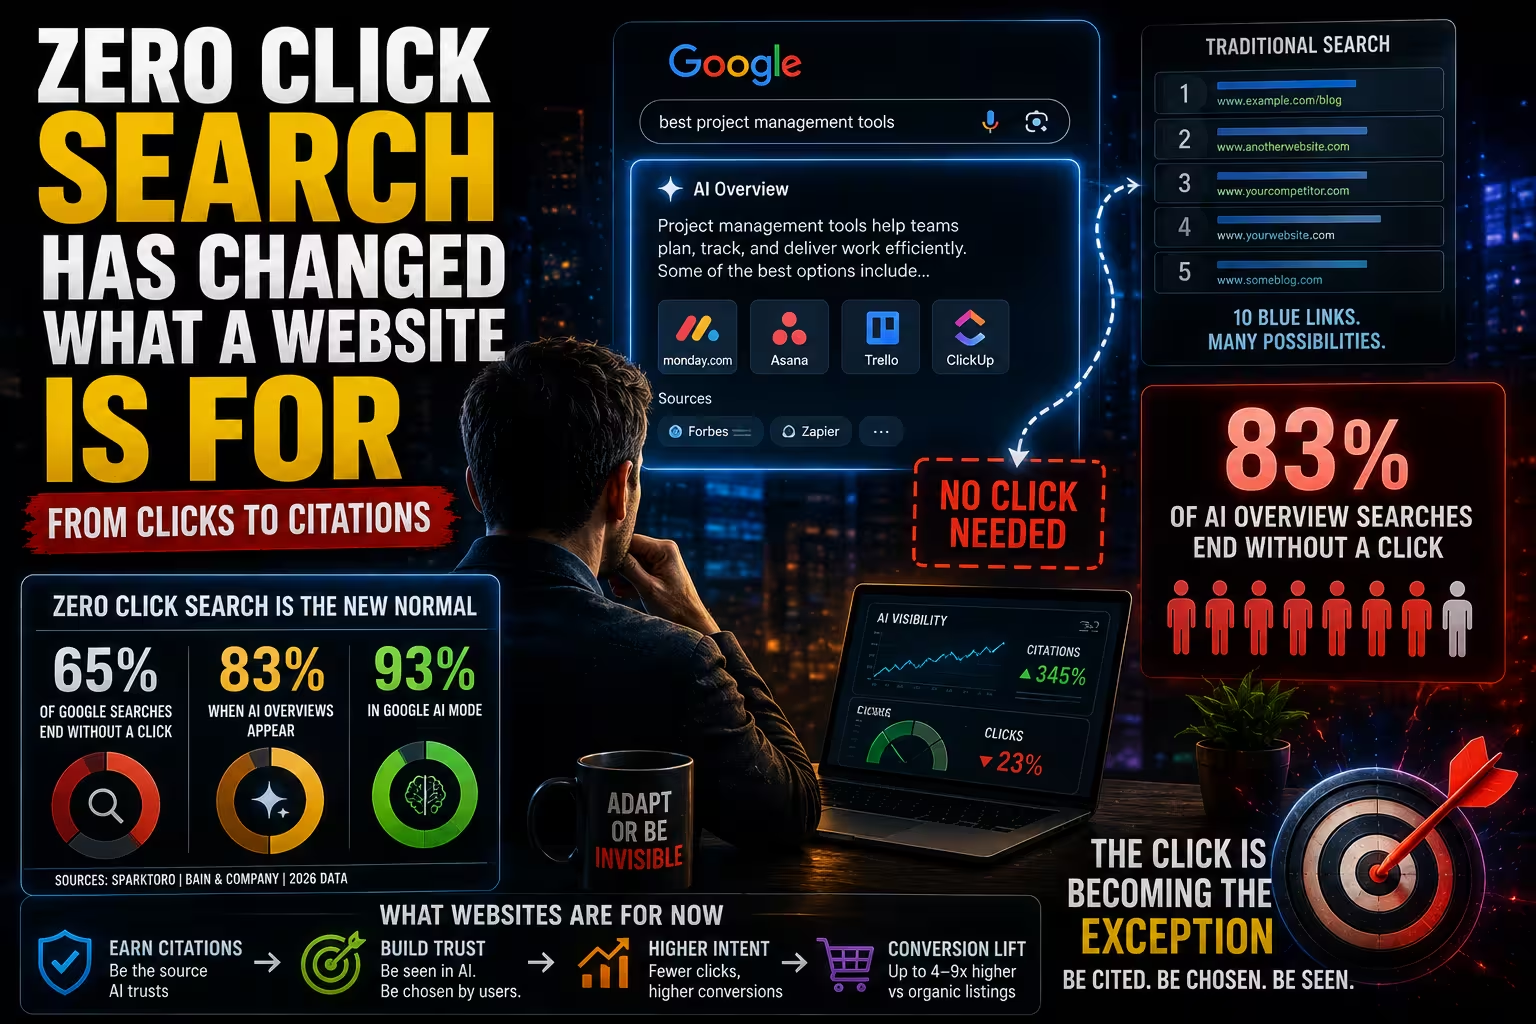
Google’s strength lies in authority signals and recency. If information is unavailable, the engine surfaces alternatives or nothing at all. LLMs generate a response regardless, prioritising conversational relevance. This enables zero-click experiences and contextual summaries, but increases exposure to misinformation (IMD, Nov 2025). In commerce, AI search personalises recommendations but remains marginal, accounting for less than 5% of queries in 2025 (TTMS Forecast, Aug 2025).
The overlap between Google rankings and LLM citations sits between 7–21%, meaning success in one system does not translate reliably to the other (Search Engine Journal, Nov 2025). Businesses optimising solely for traditional SEO risk invisibility in AI answers, while those chasing AI visibility without authority signals amplify hallucination exposure.
What is the current financial impact to businesses from AI Hallucinations?
The economic cost of hallucinations has moved from anecdotal to systemic. Losses are projected to exceed $100 billion in 2025, driven by failed projects, reputational damage, and operational inefficiency (Korra.ai Report, Aug 2025). McKinsey’s 2025 survey shows 70–85% of AI initiatives fail to deliver expected value, with hallucinations cited as a contributing factor in the majority of cases (Fullview.io, Nov 2025).
As Sarah Johnson of Deloitte observed, “Hallucinations are a business risk that can wipe out brand building overnight” (Knostic Blog, June 2025). The cost is not limited to error correction. It includes lost trust, delayed adoption, and increased governance overhead, all of which suppress return on investment.
Which Sectors are affected the most from AI Hallucinations?
Different industries absorb hallucination risk unevenly. In commerce and services, fabricated recommendations and incorrect product details drive 15–20% revenue loss through cart abandonment, while 25% of users abandon AI tools after a single error (McKinsey, Nov 2025). Viral misinformation amplifies customer support costs and damages brand equity.
Healthcare faces sharper consequences. False positives and negatives occur in 10–15% of AI-assisted assessments, exposing providers to litigation and fines exceeding $1 million per incident (medRxiv, Mar 2025). These failures undermine clinical confidence, slowing adoption despite efficiency gains.
Financial services record over $500 million in trading and reporting errors linked to hallucinated outputs, while compliance costs rise 20–30% due to increased audit scrutiny (Novaspivack, May 2025). Legal services remain the most exposed. More than 58 cases of hallucinated citations appeared in court filings during 2025, leading to sanctions and a 40% increase in research time (Stanford HAI, Jan 2024 with 2025 trend updates). Across sectors, businesses now spend 10–15% more on oversight to contain these risks (AEI, Sept 2025).
What We as Search Marketers are doing differently
Search marketing for AI systems demands a shift from keyword dominance to answer credibility. Answer Engine Optimisation prioritises content structures that LLMs can parse and trust. Conversational formats, explicit question framing, and structured data improve citation likelihood when models assemble responses (Conductor Academy, Sept 2025).
Authority matters more than volume. Original research, consistent brand entities, and citations from high-trust platforms increase the probability that AI systems reference a business accurately. Crawlability remains essential, with AI-specific bots requiring monitoring alongside traditional search crawlers (Lumar, Nov 2025). Supplying proprietary, verifiable data reduces the chance that a model fills gaps with invention, while ongoing brand monitoring identifies hallucinated mentions before they propagate (Search Engine Land, June 2025).
“Businesses that ignore hallucinations will be cited incorrectly”
Geoff Parker, Managing Director of Blue Ocean Media, frames the issue as one of visibility rather than novelty. “AI systems will answer questions whether your business participates or not,” he says. “If your data is unclear or absent, models will fill the gaps. That is how brands end up being cited incorrectly, or not at all. Search optimisation now means controlling facts, not chasing clicks”.
AI hallucinations will define trust in search The defining feature of AI search optimisation in 2025 is not speed or fluency, but trust. With losses exceeding $100 billion, hallucinations have become a commercial constraint rather than a technical curiosity. Businesses that treat AI answers as neutral outputs inherit risk they cannot see. Those that invest in authority, structure, and verification position themselves to benefit from AI visibility without absorbing its failures. The systems will continue to speak. The question is whose facts they repeat.